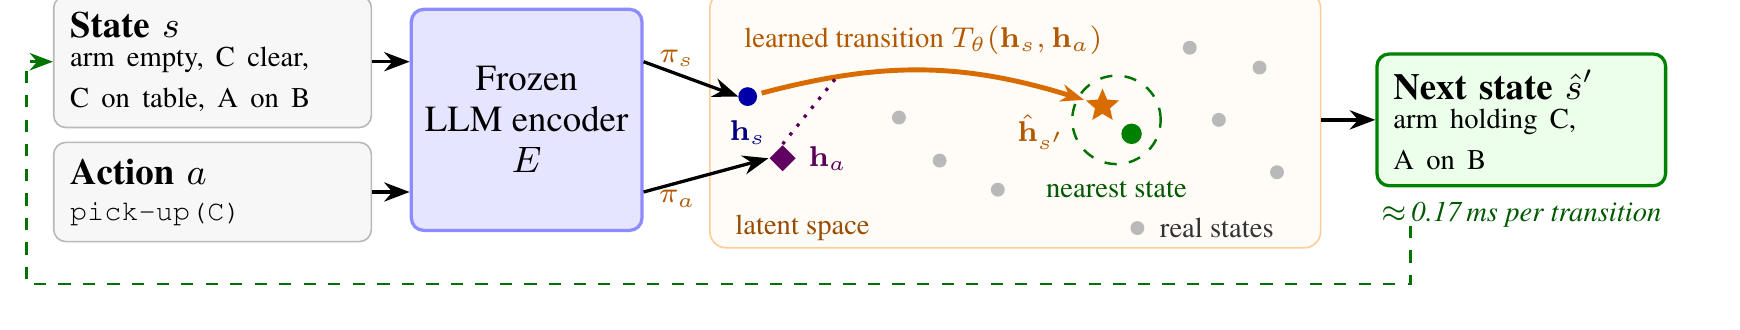
When a large language model serves as a planner's transition model, every next state is generated token by token, which makes searching over many possible futures slow and expensive. EmbedPlan embeds the state and action with a frozen LLM, predicts the next-state embedding with a lightweight learned network, and returns the closest real state, evaluated on 9 classical planning domains under six settings that hold out progressively more of the data.
Hit@5 within observed problems: the true next state ranks in the top 5 of 128 candidates (Interpolation, Llama-3.3-70B, chance 3.9%).
of step accuracy kept when each prediction is fed back as the next input, snapped to the nearest real state (Ferry, Logistics, Blocksworld, observed problems).
Hit@5 on unseen domains (Cross-Domain), near the 3.9% chance level, against 54.6% on unseen problems of an observed domain.
per transition with cached state embeddings, against 1.9 s for generating the next state through an LLM API.
Abstract
Planning requires a transition model that predicts how each action changes the current state. When a large language model (LLM) plays this role, every next state is generated token by token, which makes searching over many possible futures slow and expensive. Existing alternatives either still query an LLM at every step or require a symbolic model of the domain. We propose EmbedPlan, a transition model built on frozen text embeddings: it embeds natural language descriptions of the state and the action with a frozen LLM, predicts the embedding of the next state with a lightweight learned network, and returns the closest real state. Because this network can be trained on top of any encoder, EmbedPlan also provides a controlled way to compare text representations for learning transitions. We evaluate it on 9 classical planning domains, under six settings that hold out progressively more of the data, from transitions to entire domains, and against baselines ranging from predicting no change to learning symbolic action rules. On planning problems seen during training, EmbedPlan almost always ranks the true next state among its top five guesses, still does so for most queries even when every observed state is a candidate, and retains 92–99% of its single-step accuracy when predicting several steps ahead from its own outputs. Given the same candidate states as GPT-5.4, it picks the true next state more often while taking about 0.17 ms per transition with cached embeddings. Accuracy is lower on unseen problems and near chance on unseen domains, and the controlled comparison traces this limit to the state representation rather than to the learned transition.
The idea
Planning needs a transition model that predicts how each action changes the current state. When a large language model plays this role, each next state is generated token by token, with a full forward pass per token, which makes multi-step lookahead and search expensive in latency and cost.
EmbedPlan keeps the semantic encoding in a frozen LLM and learns only the cheap dynamics. It predicts the embedding of the next state with a small network and returns the closest real state, so every prediction is a real state. Because the same head can be trained over any encoder, the framework also serves as a controlled probe of what a frozen text representation supports for learning dynamics.
How it works
- A frozen LLM encoder embeds a natural language description of the state and of the action, for example a Blocksworld state and the action
pick-up(C). Each state prompt holds the problem and goal description followed by the facts that hold. - Learned state and action heads project both embeddings into a 128-dimensional latent space.
- A residual MLP with fewer than 500K parameters predicts the embedding of the next state.
- The nearest state in a candidate pool, by cosine similarity, is returned as the successor. Fed back as the next input, it supports multi-step rollout.
- Two contrastive objectives train the head: state prediction, which identifies the correct next state among candidates, and action disambiguation, which separates the effects of different actions on the same state.
EmbedPlan is a transition component, not a complete planner. Search composes many transitions, and the paper studies the single transition that search queries repeatedly. Training is per domain: a one-time embedding pass plus about 15 minutes of training.
How it was tested
The data are nine classical PDDL domains from ACPBench, with states rendered as natural language: Blocksworld, Depot, Ferry, Floortile, Goldminer, Grid, Logistics, Rovers and Satellite. Together they give 2.97M transitions over 67 problems (259K unique states). A domain fixes the action schemas, and a problem fixes the objects, the initial state, and the goal.
Four frozen encoders are compared: MPNet (all-mpnet-base-v2), BGE-M3, Qwen2.5-7B and Llama-3.3-70B. Results use Llama-3.3-70B unless another encoder is named.
Six protocols form a ladder of exposure, ordered by what the test data share with training:
- Interpolation: held-out transitions of observed problems.
- Plan-Variant: unseen optimal plans of observed problems.
- Extrapolation: unseen problems of an observed domain.
- Multi-Domain: unseen problems, with one model for all nine domains.
- Cross-Domain: an unseen domain, after training on one other domain.
- Leave-One-Out: an unseen domain, after training on the other eight.
Every query is ranked against 128 states, the true successor and 127 distractors. The reference methods keep the head and the pool and vary only the state representation, from no-change floors to lifted STRIPS induction, which serves as an oracle upper bound.
What it finds
Within observed problems, EmbedPlan has the properties search needs. Hit@5 is 99.7% with Llama-3.3-70B. When the candidate pool grows to every observed state of the domain, Hit@5 falls from 100.0% to 86.9% on Ferry (46,205 states) and from 99.9% to 74.9% on Logistics (13,373 states). Snapping each prediction to the nearest real state keeps multi-step rollout within 92–99% of the accuracy obtained with the true state at each step.
Within observed problems, EmbedPlan matches or beats every LLM tested. Given the identical ranking task over the same 128 candidates, GPT-5.4 selects the true successor for 44% of Ferry and 92% of Logistics queries, against 99.0% and 96.3% for EmbedPlan. The comparison is matched in task, not in information: EmbedPlan has observed other transitions of the same problems, whereas the LLM is zero-shot. It ranks successors 101× faster end to end than generation through an LLM API (1.9 s per transition), and takes about 0.17 ms per transition with cached state embeddings.
Accuracy falls with each step down the exposure ladder. On unseen problems of an observed domain, Hit@5 is 54.6%, 14 times chance, and it varies widely by domain (26–76%). Larger encoders extrapolate better, from 26.8% for MPNet to 54.6% for Llama-3.3-70B, but none closes the gap. On unseen domains, Hit@5 is 6.6% (Cross-Domain) and 9.2% (Leave-One-Out), near the 3.9% chance level.
With the head, data and pool fixed, the state representation decides transfer to unseen problems. On Ferry, Logistics and Goldminer, character 3–5 grams of the same text reach 79.4% Hit@5, against 56.8% with Llama-3.3-70B embeddings, and lifted STRIPS induction, given each state's symbolic facts, reaches 99.8%. On these templated states an action edits only a few facts of an otherwise identical text, which sparse and symbolic representations capture directly and a pooled LLM embedding barely registers. The paper names a concrete target for transfer to new problems: an object-aware, order-invariant state encoder.
Limitations
- EmbedPlan is a transition component for discrete, domain-specific settings, not a domain-general planner, and must be trained per domain because cross-domain transfer fails.
- Retrieval assumes a candidate pool that contains the true successor.
- The domains are templated, so the paper has not yet tested the regime the text interface is meant for: states without a clean literal decomposition, where symbolic induction and lexical features would break.
- Pool scaling, multi-step rollout, and LLM ranking are measured within observed problems, and rollouts cover short test trajectories (mean 2.2 steps).
- Extrapolation rests on one or two held-out problems per domain, and the reference comparison covers three domains, without ablating the problem and goal text that every prompt shares.
- Integrating EmbedPlan into beam or tree search over long horizons on held-out problems is the direct next step.
Use it on your data
The code includes EmbedPlan as a scikit-learn style estimator for any domain whose states and actions can be written as text, such as planning problems, game logs, web or UI agent traces, or lab protocols.
fitlearns from (state, action) pairs and their next states, with optional groups such as problem ids.predictreturns the most likely next state as text, ranked among candidate states, androlloutpredicts several steps, each snapped to the nearest real state.evaluatefollows the paper's protocol, 128 candidates per query, and reports the chance level of the same pools.- The encoder can be a hashing encoder of word n-grams that needs no download, any sentence-transformers or Hugging Face model name, or your own function from texts to vectors.
Try it with no install in the Colab notebook, or start from the repository. On unseen problems, expect lower accuracy than on seen ones: that is the paper's main finding.
Results by protocol
Hit@5 (%) with the Llama-3.3-70B encoder, mean ± SE across the nine domains. Every query is ranked against 128 candidates, so chance is 3.9%. Rows are ordered by what the test data share with training, and the gain is over chance in percentage points (pp). Plan-Variant faces the hardest distractors. From Table 5 of the paper.
| Protocol | Observed in training | Hit@5 (%) | Gain over chance (pp) |
|---|---|---|---|
| Interpolation | The problems | 99.7 ± 0.1 | +96 |
| Plan-Variant | The problems | 51.2 ± 5.5 | +47 |
| Extrapolation | The domain | 54.6 ± 5.5 | +51 |
| Multi-Domain | The domain | 37.2 ± 3.8 | +33 |
| Leave-One-Out | 8 other domains | 9.2 ± 1.2 | +5.3 |
| Cross-Domain | 1 other domain | 6.6 ± 0.5 | +2.7 |
| Chance | 3.9 |
Terms
- EmbedPlan
- A transition model built on frozen text embeddings: it embeds natural language descriptions of the state and the action with a frozen LLM, predicts the embedding of the next state with a lightweight learned network, and returns the closest real state.
- Transition model
- A model that predicts how each action changes the current state, which planning requires.
- Hit@k
- The fraction of queries whose true next state ranks in the top k of a candidate pool. Unless stated otherwise the pool holds 128 states, the true successor and 127 distractors, so chance is 3.9% for Hit@5 and 0.8% for Hit@1.
- Head
- The learned state and action projection heads and the transition network, together. Only the head is trained, and the LLM encoder stays frozen.
- Snapping
- In multi-step rollout, each state prediction is replaced by the nearest real state the model retrieves, right or wrong, and that state becomes the next input.
- Domain and problem
- A domain fixes the action schemas, and a problem fixes the objects, the initial state, and the goal.
- Grounded action
- An instance of a lifted action schema with its objects filled in, such as
pick-up(C)for the schemapick-up(?x). - Interpolation
- The protocol that trains on 80% of a domain's transitions and tests on the other 20%, held out at random, so test transitions come from observed problems, with distractors from the whole domain.
- Plan-Variant
- The protocol that trains on some optimal plans and tests on other optimal plans of the same problems, with distractors from successors along alternative optimal plans, the hardest distractors the paper uses.
- Extrapolation
- The protocol that trains on about 80% of a domain's problems and tests on the other 20%, so test transitions come from unseen problems, with distractors from the query's own problem.
- Multi-Domain
- Extrapolation with one model for all nine domains at once.
- Cross-Domain
- The protocol that trains on one domain and tests on another, with distractors from the target domain.
- Leave-One-Out
- The protocol that trains on eight domains and tests on the ninth, with distractors from the target domain.
- Identity and Offset
- Two non-learned floors that need no training. Identity predicts the current state's embedding, and Offset adds the mean training displacement of the ground action or of its schema.
- Lifted STRIPS induction
- A reference method that infers each action schema's add and delete effects from the symbolic facts of each state. It serves as an oracle upper bound.
- Action disambiguation
- A training objective that separates the effects of different actions on the same state: the true action must yield a prediction closer to the next state than up to 50 alternative actions applied to the same state.
Questions
What is EmbedPlan?
EmbedPlan is a transition model for planning built on frozen text embeddings. Given a state and an action described in natural language, a frozen LLM embeds both, a lightweight learned network predicts the embedding of the next state, and the closest real state is returned. It is a transition component, not a complete planner: search composes many transitions, and the paper studies the single transition that search queries repeatedly.
Why not let an LLM generate the next state?
Because generating every next state token by token makes search slow and expensive. When an LLM serves as the world model of a planner, each next state is generated with a full forward pass per token, which makes multi-step lookahead and rollout-based search prohibitively expensive in latency and cost. EmbedPlan leaves the semantic encoding to the frozen LLM and learns only the cheap dynamics, so each prediction is one learned vector step followed by retrieval.
Is EmbedPlan better than asking an LLM like GPT-5.4?
Within observed problems, at picking the true next state, yes. Given the identical ranking task over the same 128 candidates, GPT-5.4 selects the true successor for 44% of Ferry and 92% of Logistics queries, against 99.0% and 96.3% for EmbedPlan. On Logistics the margin is small next to the spread across the paper's runs (91.2–96.3%). The comparison is matched in task, not in information: EmbedPlan has observed other transitions of the same problems, whereas the LLM is zero-shot, and on unseen problems its Ferry Hit@1 falls to 12.0%.
How fast is EmbedPlan?
About 0.17 ms per transition with cached state embeddings, 11,215× faster than generating the next state through an LLM API (1.9 s per transition). End to end, including encoding the query texts with BGE-M3, it takes 18.6 ms, 101× faster. Training is a one-time cost per domain, an embedding pass plus about 15 minutes of training, which breaks even against autoregressive generation after about 4,300 transitions with Llama-3.3-70B, so it pays off for a domain that is planned in repeatedly.
What does Hit@5 measure, and what is chance?
Hit@5 is the fraction of queries whose true next state ranks in the top 5 of a candidate pool. Unless stated otherwise the pool holds 128 states, the true successor and 127 distractors, so chance is 3.9% for Hit@5 and 0.8% for Hit@1. The paper emphasizes Hit@5 because it is robust to the pool size, and a top-5 list is also useful where a verifier can filter candidates.
How well does EmbedPlan generalize to new problems and new domains?
It depends on what the model has seen. With the Llama-3.3-70B encoder, Hit@5 is 99.7% on held-out transitions of observed problems, 54.6% on unseen problems of an observed domain, and 6.6% on unseen domains, near the 3.9% chance level. Training on the other eight domains (Leave-One-Out) reaches 9.2%. One model trained on all nine domains reaches 37.2% on their unseen problems.
What limits transfer to unseen problems and domains?
The paper traces the limit to the frozen state representation rather than to the learned transition. With the head, data and pool fixed, character 3–5 grams of the same text reach 79.4% Hit@5 on unseen problems of three domains, against 56.8% with Llama-3.3-70B embeddings. On unseen domains, the paper sees two plausible causes that its experiments do not separate: frozen embeddings organize states by surface form rather than by structural role, and the learned action semantics are domain-specific.
Does EmbedPlan stay accurate over several steps?
Yes, over short horizons, when each prediction is snapped to a real state. If each predicted state is replaced by the nearest real state before the next step, rollout keeps 92–99% of the accuracy obtained with the true state at each step, on Ferry, Logistics and Blocksworld within observed problems. Without snapping, the predicted embedding drifts off the real states. The test trajectories are short (mean 2.2 steps on Ferry), so this establishes stability over short horizons only.
Does the true next state have to be among the candidates?
Yes. Retrieval assumes a candidate pool that contains the true successor. The paper measures how accuracy degrades as the pool grows to every state observed in a domain. On Ferry (46,205 states), Hit@5 falls from 100.0% to 86.9%, and on Logistics (13,373 states) from 99.9% to 74.9%, while Hit@1 falls to 35.2% and 32.6%. The true successor thus stays in a short list against the full pool, though not reliably at rank one.
Which domains and encoders does the paper use?
Nine classical PDDL domains from ACPBench, with states rendered as natural language: Blocksworld, Depot, Ferry, Floortile, Goldminer, Grid, Logistics, Rovers and Satellite, 2.97M transitions over 67 problems. The frozen encoders are MPNet (all-mpnet-base-v2), BGE-M3, Qwen2.5-7B and Llama-3.3-70B. Larger encoders extrapolate better, from 26.8% Hit@5 on unseen problems with MPNet to 54.6% with Llama-3.3-70B, but none closes the gap.
When is EmbedPlan worth using?
When states and actions are available as text but no symbolic model is, so that the alternative is querying an LLM at every expansion. Action selection and search remain external to EmbedPlan. It must be trained per domain, with a one-time embedding pass plus about 15 minutes of training, so it pays off for a domain that is planned in repeatedly. The paper's classical domains have exact simulators, which makes them a controlled testbed.
When EmbedPlan misses, how far off is its top guess?
By a few facts. When the true successor misses the top five on unseen problems, the top-ranked state typically differs from it in one to three facts (median 2), usually involving object locations or holdings within the same problem instance. These errors suggest the model captures coarse transition structure (correct problem context, approximate state region) but struggles to resolve fine-grained predicate changes, particularly when multiple objects undergo similar transformations.
Would fine-tuning the encoder help?
Adapting the encoder already helps. Low-rank adaptation (LoRA) of BGE-M3 raises full-pool Hit@1 on unseen problems from 3.8% to 9.3% when the head is first trained with the encoder frozen, and to 6.2% with a cold joint start. Larger frozen encoders also extrapolate better. Because the encoder is a plug-in, the paper names a concrete target the framework can evaluate directly: an object-aware, order-invariant state encoder.
Can EmbedPlan tell apart the effects of different actions?
Within observed problems it mostly can, and on unseen problems far less often. The paper applies every action applicable in a state and ranks the actions by how close their predictions come to the true next state. Acc@k is the fraction of queries whose true action ranks in the top k. Mean Acc@5 is 85.3% within observed problems (Acc@1 32.0%) and 16.2% on unseen problems, where training without the action loss reaches only 4.8%.
How often does EmbedPlan get a whole plan right?
Under Plan-Variant, where the plans are unseen but their problems are observed, 22.6% of plans are correct at every step and mean per-step Hit@5 is 51.2%. Each step is ranked against successors along alternative optimal plans, the hardest distractors the paper uses: they are reachable and often differ from the target in a single fact. Plans of unseen problems fare far worse, at 10.1% per step and 3.3% of plans.
Citation
@article{shlomi2026textual,
  title   = {Textual Planning with Explicit Latent Transitions},
  author  = {Shlomi, Eliezer and Levy, Ido and Shapira, Eilam and Katz, Michael and Uziel, Guy and Shlomov, Segev and Mashkif, Nir and Reichart, Roi and Keren, Sarah},
  journal = {arXiv preprint arXiv:2602.04557},
  year    = {2026}
}